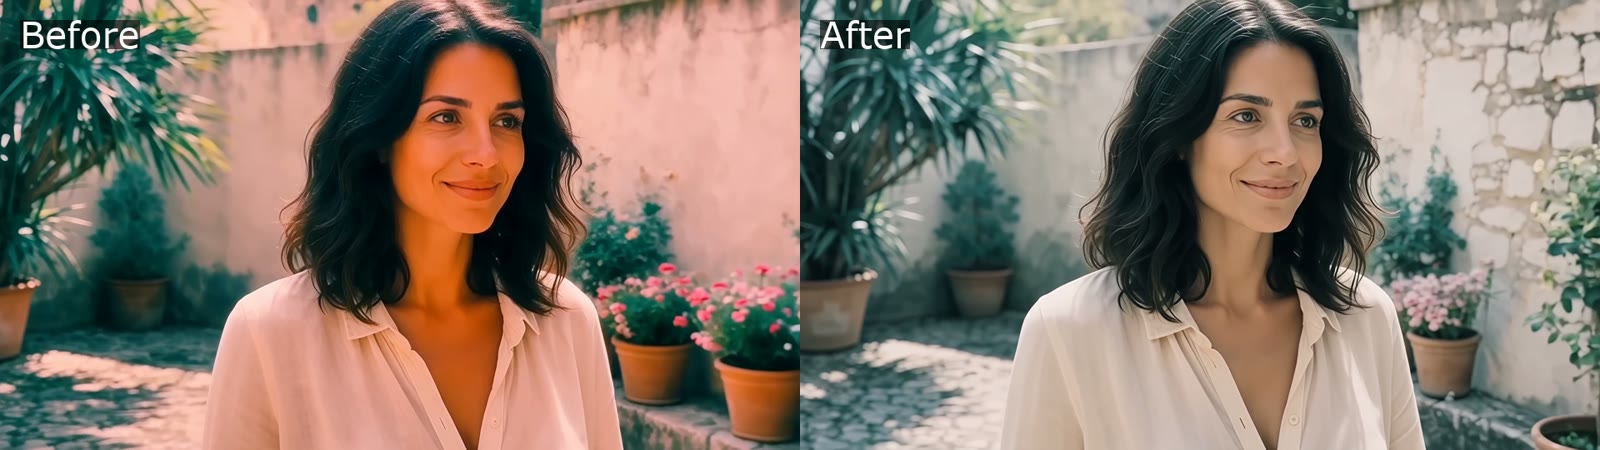
Learn how to break down framing, depth, color, and camera movement with AI, then rebuild those decisions as stronger prompts for generated video.
Most AI video clips fail for an unglamorous reason: nobody designed the frame. The prompt named a subject and a mood, the model returned something plausible, and the result reads like a screenshot rather than a shot. Deconstructing composition with AI fixes that. Instead of guessing why a reference frame works, you can measure it — where visual weight sits, how deep the space reads, which light source owns the eye — and then rebuild those decisions inside your own generation.
What follows is a working method, not a theory tour. You will see what a vision model can genuinely extract from a frame, how to turn those findings into prompt language, how to compare variants without drowning in options, and where human judgment still outperforms any automated read.
Why composition analysis belongs in the generation loop
Traditional analysis happens after the fact. You shoot, you edit, someone says the frame feels flat, and nobody can articulate why. Generation reverses that order: the frame is described before it exists. That makes analysis more valuable, not less, because every observation can be applied on the very next render.
Three things change when you put analysis inside the loop:
- Vocabulary stops being decorative. Cinematic is not an instruction. A medium shot at eye level, subject on the left third, 35mm compression, single hard key from frame right at roughly 45 degrees, background two stops down — that is an instruction.
- Iteration becomes directional. Without analysis you re-roll and hope. With it, you change one variable — camera height, or the falloff on the background wall — and you can see whether the frame actually improved.
- Style becomes reusable. A deconstructed reference turns into a short document you can reuse across a series, so episode four looks like episode one without re-deriving everything from mood.
There is a limit worth stating early: AI reads structure well and intention poorly. It can tell you the horizon sits at roughly 0.62 of frame height and the key light is 40 degrees camera left. It cannot tell you whether a character's hesitation should be visible in the shoulders. Keep that division of labor in mind and the tool stays useful.
What an AI read of a frame can actually measure
Modern vision models describe a still with surprising precision, and video models add temporal structure on top. The useful outputs cluster into four families.
Balance, weight, and negative space
Ask for weight distribution and you get something actionable: subject mass occupies the right third, the left third is empty wall, the top fifteen percent is dead ceiling. From there you can judge whether the empty space is doing work — holding a title, isolating a figure, delaying a reveal — or simply wasting frame.
A practical test: cover the subject with your thumb. If the remaining frame still has a shape, the composition is designed. If it collapses into nothing, the frame was only ever a subject.
Depth, lens language, and layers
Depth is the most under-specified element in AI prompting and the biggest reason generated clips look like cardboard. Analysis helps you name the layers explicitly:
- foreground element, such as a doorframe edge, a shoulder, or a curtain
- midground subject
- background plane, and how far down it sits in exposure
- atmospheric separator — haze, dust, rain, defocused highlights
It also helps you infer the lens. A wide, close, slightly distorted face with a receding room reads like a 24mm at short distance. A compressed background with soft falloff reads like an 85mm. You do not need exact millimeter accuracy; you need the relational cue, because that is what you will write into the prompt. Our prompt library is organized around these relational cues rather than lens trivia.
Light direction, color, and contrast
Lighting analysis is where AI most often earns its keep, because humans are bad at reverse-engineering light. Ask for key direction, fill ratio, color temperature split between key and ambient, and the position of the brightest highlight. Typical output: key from upper frame right, warm at 3200K, ambient cool at 5600K spilling from a window, background two stops under the subject.
That single sentence is directly renderable. It also explains the mood, which is the part people usually try to describe with adjectives and fail.
Motion and camera path
With video, analysis extends to movement: does the camera push, drift, or hold? Does the subject move through a static frame, or does the frame follow? Is the motion lateral, axial, or orbital? Naming the move prevents the most common generated-video defect — a camera that wanders because the prompt implied drama without specifying direction.
A five-step deconstruction workflow
Here is the loop, in order. It works whether you are rebuilding a reference shot or pressure-testing an original idea.
Step one: build a reference set of eight to twelve frames
Small, deliberately chosen, and consistent in intent. If you are making a night chase, your set should be night exteriors and wet streets, not a museum of favorite films. Eight frames is enough to reveal a pattern; forty becomes a mood board nobody reads.
For each frame, note one sentence about why it is in the set. That sentence is your ground truth, and it protects you from confident but irrelevant observations.
Step two: extract the skeleton, not the story
Run each reference through analysis asking for structural facts only: framing scale, subject placement, horizon height, layer count, key direction, contrast ratio, dominant and accent color, camera height relative to subject. Ignore narrative commentary. You are collecting anatomy.
Then reduce the set. If six of eight frames put the subject in the lower left with a dominant vertical on the right, that is your series grammar, and it should appear in every prompt you write.
Step three: convert findings into a prompt stack
Write prompts in a fixed order so you can vary one line at a time: shot scale, subject placement, lens and distance, light direction and quality, color relationship, background layers, motion. Keeping the order stable turns prompting into a controlled experiment instead of a slot machine.
Step four: generate in tight batches
Render three to five variants per change, never thirty. With a small batch you can attribute differences. With a large batch you get a favorite and no idea why it won. Compare against your one-sentence ground truth, not against a feeling.
Step five: lock the look with a style sheet
When a variant works, record the exact prompt lines that produced it, plus two or three stills. That document becomes your series bible. On the next shot you change only the narrative variables — subject, action, location — and keep composition and light fixed. This is how consistency is actually achieved in generated video: not by re-describing the mood, but by reusing structural decisions.
Turning analysis into prompt language
There is a gap between an analysis and a usable prompt, and most people lose the benefit right there. Three before-and-after examples.
Weak: a detective in a dark office, cinematic lighting. Improved: medium shot, detective seated at frame left, desk lamp as hard key from frame right, face half lit, background shelving two stops underexposed, 40mm at chest height, static camera.
Weak: epic landscape with a traveler. Improved: extreme wide, traveler occupying the lower right sixth, horizon at two thirds height, foreground rock layer at the frame left edge, midground ridge, distant peaks in haze, low sun behind camera at 20 degrees for long shadows, slow lateral drift left to right.
Weak: close-up of a woman crying, emotional. Improved: close-up, eyes on the upper third line, slightly off-center right, soft window light from camera left with cool ambient fill, background dissolved into a flat dark plane, 85mm compression, camera height at eye level, no movement.
The pattern is consistent: replace the adjective with a spatial fact, then let the model do the feeling. Emotion in a frame is usually a byproduct of light ratio, distance, and where the eyes sit — not of the word emotional.
One extra habit helps. After every successful render, re-run the analysis on your own output and compare it with your prompt. When the model quietly adds a second light source or lifts the shadows, you will see exactly which line needs to become more explicit next time.
Case study: rebuilding a corridor confrontation
Assume a reference: two figures facing each other in a narrow corridor, one lit, one in shadow.
Analysis pass. Framing is a medium two-shot at chest height. The lit figure sits on the left third, the shadowed figure on the right third, with the corridor vanishing point dead center creating symmetric pressure. The key is a practical overhead fixture, hard, warm, roughly 30 degrees above the lit figure. The right side falls off by three stops. A foreground vertical — a doorframe — clips the left edge, adding depth and mild claustrophobia.
Reduction. The shot grammar is: central vanishing point, opposed figures on thirds, extreme exposure asymmetry, one foreground occluder, no camera movement.
First render. Ask for exactly that grammar. Expect the model to over-light the shadowed figure; generated video dislikes leaving half the frame dark. Correct by stating the exposure relationship and specifying no fill on the right side.
Second render. With the ratio enforced, add one micro-adjustment: move the camera 15 centimeters lower so the ceiling line drops and the corridor feels tighter. Regenerate three variants.
Lock. Save the winning prompt lines as corridor confrontation, symmetric, hard practical, three-stop split. The next scene in the same location reuses it with a new action line.
That is the whole method in miniature: read the structure, reduce it to grammar, render, correct the model's known biases, adjust one variable, then save the result as reusable language. If you want to see how it plays out across a longer piece, the AI video generator workspace is where batch comparisons happen, and video templates are useful when you need a starting grammar rather than a blank prompt. Still frames for reference sets can be built with the AI image generator when you cannot find the exact composition you want.
Choosing tools for analysis-driven generation
Most generators can produce a beautiful single frame. Fewer support the loop described above. When evaluating a tool, separate the analysis layer from the generation layer.
What matters in the analysis layer
- Structured output. You want fields — placement, layers, ratio, light direction — not a paragraph of praise.
- Re-runnability. The same frame analyzed twice should give similar numbers. Inconsistent measurement is worse than none.
- Video awareness. A tool that only reads stills will miss camera path, which is half of temporal composition.
What matters in the generation layer
- Prompt adherence over spectacle. A model that honors camera height and exposure ratio beats one that produces prettier defaults.
- Fast cheap iteration. You need many small batches. If each render takes ten minutes, the loop dies.
- Consistent style input. Reference images or saved presets let you reapply a locked look instead of retyping it.
- Aspect ratio flexibility. If you publish vertical, confirm the tool respects placement instructions after the crop changes.
A note on iteration speed
Speed is not a luxury here; it is the method. Analysis-driven work depends on comparing near-identical variants. A workflow that takes an hour per idea cannot support five-step deconstruction, and you will quietly drift back to one-shot prompting. Test your loop end to end before committing to a tool: analyze one frame, write one prompt, render three variants, adjust one line, render three more. If that cycle fits inside fifteen minutes, the workflow will survive contact with a deadline.
Decision criteria: analyze, borrow, or build from scratch
Not every shot deserves the full workflow. Use these thresholds.
| Situation | Recommended approach |
|---|---|
| Series work with a recurring look | Full deconstruction plus style sheet |
| Single hero shot with a clear reference | Analyze one frame, run two render batches |
| Fast social iteration | Borrow grammar from one frame, skip metrics |
| Early style exploration | Generate broadly first, analyze only winners |
Three questions decide it faster:
- Will you make this shot more than once? If yes, build the style sheet.
- Can you articulate why the reference works? If not, analyze before prompting.
- Is the constraint technical or emotional? Technical constraints — ratio, lens, layer count — are worth specifying. Emotional ones are usually better left to the model.
Mistakes that flatten a composition
- Describing mood instead of space. Moody produces a color grade, not a composition.
- Filling every layer. Generated scenes often add clutter to the background. Say what should be empty.
- Ignoring camera height. Hip height versus eye level changes the emotional read of the same subject more than most lighting choices.
- Centering by default. Center framing is powerful and specific; used carelessly it reads as a passport photo.
- Even exposure. If nothing is two stops down, nothing leads the eye.
- Changing five variables at once. You will get a better image and no knowledge.
- Trusting the analysis over your eyes. Models hallucinate lens data confidently. If the frame looks like a 50mm, it is a 50mm.
- Forgetting the crop. A composition designed for widescreen rarely survives a vertical reframe. Redo placement whenever the aspect ratio changes.
A short pre-render checklist
Run this before every batch:
- shot scale named, in one word
- subject position named against a third or center line
- camera height named relative to subject
- one key direction and one fill ratio stated
- background described as layers, with a stated exposure gap
- one deliberate emptiness in the frame
- motion named, or static stated explicitly
- one narrative variable isolated for this batch
If any line is missing, the model will fill it with an average — and averages are exactly what makes generated footage forgettable.
FAQ
Can AI really understand composition, or is it pattern matching? It matches patterns extremely well and understands intention poorly. Treat its output as measurement, not interpretation. Measurements are reliable enough to prompt from; interpretations need your judgment.
Do I need to analyze references at all if I can just describe the shot? Describing from memory reproduces clichés. Analysis surfaces specifics you would not have thought to mention — the exact exposure gap, the occluder at the frame edge, the horizon height.
How many references should I analyze? Eight to twelve for a series, one to three for a single shot. Beyond that you are collecting rather than deciding.
Does this work for animation and stylized footage? Yes, with one adjustment: replace lens language with perspective language. Stylized work still obeys layer count, weight distribution, and light direction; it simply does not obey real optics.
What about vertical and square formats? Redo the analysis. A composition built for a wide frame rarely survives a crop. Rebuild with the same grammar but new placement — typically tighter on the subject, with negative space moved above or below.
How do I keep a consistent look across many clips? Freeze the structural lines and vary only action and location. Consistency in generated video comes from repeated geometry, not repeated adjectives.
Is analysis useful when I generate from scratch with no reference? Yes — run it on your own outputs. Analyze your best three renders, extract the shared grammar, and you have a style sheet derived from your own work rather than someone else's film.
Where should I start if I only have ten minutes? Take one frame you admire. Ask for placement, layer count, light direction, exposure gap, and camera height. Write those five facts into a single prompt in that order. Render three variants. You will already see the difference.
Build the frame before you render it
Composition is the cheapest thing to fix and the most expensive thing to ignore. A few minutes of structured analysis — placement, layers, light direction, exposure gap, motion — replaces an hour of re-rolling prompts and hoping the model stumbles into something that looks intentional.
Start with one reference frame you admire. Ask what it measures. Write those measurements as a fixed prompt order. Render a small batch, change one line, compare, then save the winner as reusable language. That loop is the entire discipline, and it compounds: ten saved style sheets will carry an entire series, and a habit of naming structure will improve every frame you describe.
When you are ready to put it into practice, open Orelon and generate the frame you actually designed — cinematic ideas in motion, built from decisions rather than adjectives.